Generative models, prompting, agents and AI tool capabilities.
Back to discovery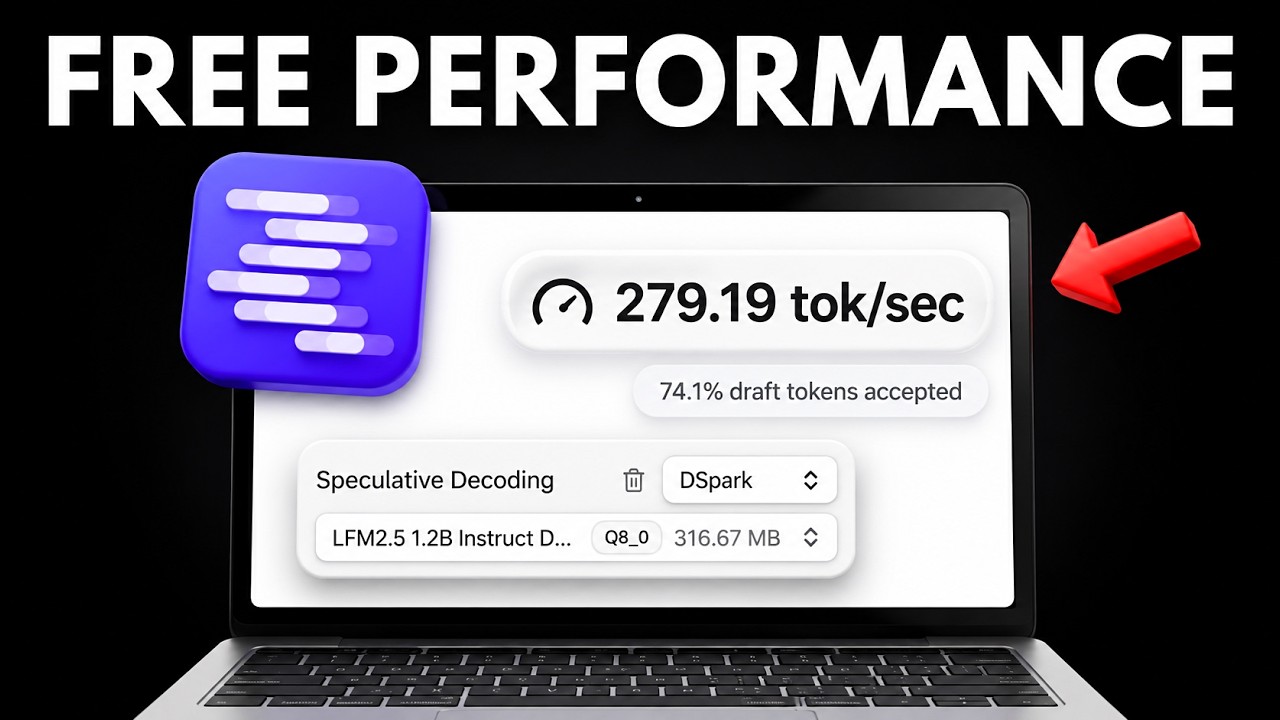 14:46
ABOUT THE CHANNEL Primary niche  AI For Humans47.8K
 Roboverse149K
 Brad Bonanno | AI Automation22.3K
14:46Technology & Computing / VIDEO AsapGuide· 26.1K subscribers
How to Make Local AI Models 2X FASTER with DFlash & DSpark in LM Studio
AsapGuide· 26.1K subscribers2d ago · en-US audio
👉 In this video, I will show you how to run speculative decoding with DFlash and DSpark drafter models in LM Studio to speed up local LLMs like Gemma, Qwen, and LFM. I also compare them with MTP and share real tokens per second results, including a case where the drafter made generation slower. If you want quicker responses from a model running on your own PC, this gives you a realistic look at what works today and…
AsapGuide
I make AI tutorial videos
4.9×Score at discovery
5.4KViews
1.1KMedian · 43 videos
Outlier score
This score was measured on Tue, 27 Oct 2026 10:33:51 GMT. Current view counts may differ.
5.3K views ÷ a 1.1K baseline = 4.9×. Compared with 43 earlier videos from the same channel, matching the format recorded at scoring time. Older-upload baseline: reference videos had at least as long to gain views. This comparison is not age-matched.
YouTube snapshot: Tue, 27 Oct 2026 12:09:05 GMT. Counters may have changed.
Read the methodologyArtificial Intelligence & Data
Channel-balanced percentile: 42
Comparison details
22 videos from 21 other channels, with each channel weighted equally. Same format and language, with 10,000–99,999 subscribers. Observed at 67 hours after publication, within ±13 hours.
The comparison uses this broader topic because the specific niche has too few examples. This describes the collected sample, not all of YouTube. Updated Tue, 27 Oct 2026 12:57:10 GMT.
Niches & tags
Transcripts and detailed analytics are available for recent outlier Shorts up to three minutes. Research tools
Breakouts from other channels
43.3×240.8 views / hour
Percentile 100 · Artificial Intelligence & DataThis Documentary Was Made Entirely by AI. Including Her.
AI For Humans47.8K
7.0×321 views / hour
Score at discovery · 2026-10-26
Percentile 97 · Generative AI & AgentsHow to Make Cocomelon Style Videos With FREE AI Tools
Roboverse149K
16.9×10.9 views / hour
Percentile 95 · Generative AI & AgentsHow I Watch ANY Video with AI in Seconds
Brad Bonanno | AI Automation22.3K