Generative models, prompting, agents and AI tool capabilities.
Back to discovery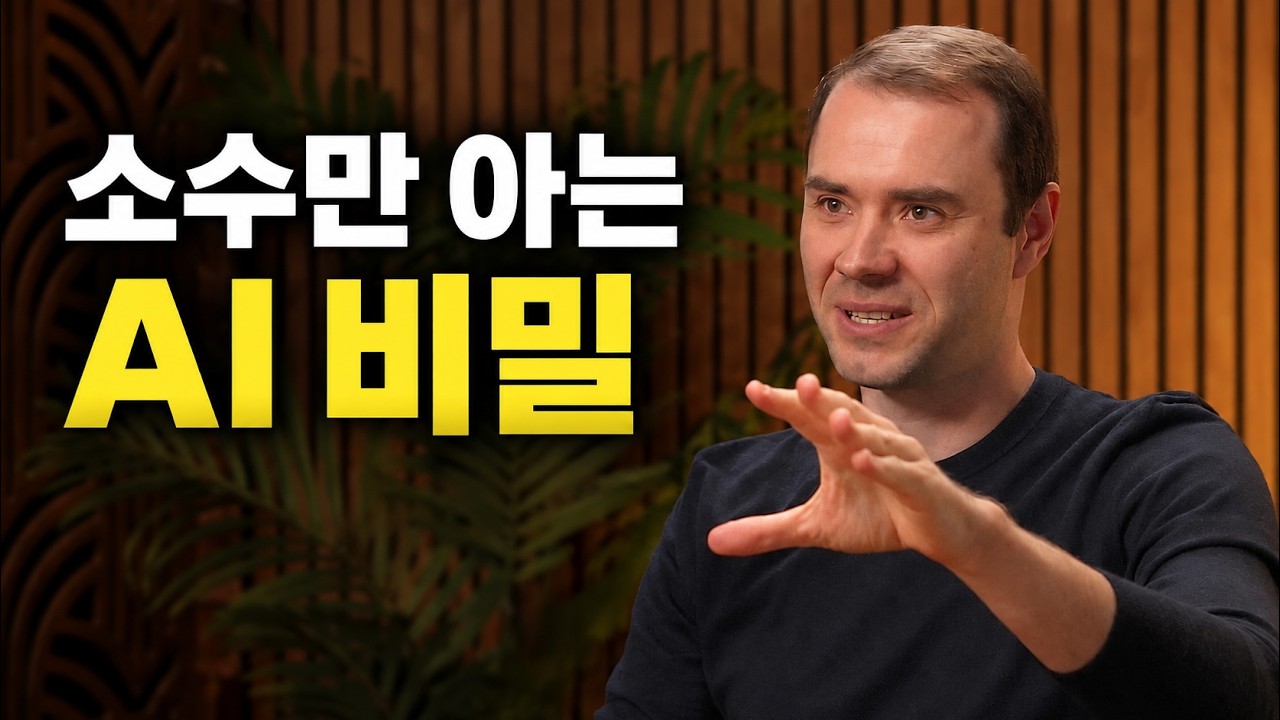 4:22
ABOUT THE CHANNEL Primary niche  생존AI31.6K
 스마트대디_SmartDaddy97.1K
 조팀장의 AI 공략집87.6K
4:22Technology & Computing / VIDEO 평범한 사업가· 39.8K subscribers
안드레 카파시가 말하는 AI 격차|사람마다 LLM 평가가 다른 이유
평범한 사업가· 39.8K subscribers16d ago · ko audio
카파시가 말하는 AI 격차는 단순히 잘 쓰는 사람과 못 쓰는 사람의 차이가 아닙니다. LLM(대규모 언어 모델)을 가벼운 검색·글쓰기 도구로 경험하는 사람과 수학·코딩에서 에이전트를 쓰는 전문가가 왜 다른 평가를 내리는지 살펴봅니다. 이 영상은 안드레이 카파시의 글을 한국어로 전달하며, 이용 경험을 네 단계로 나누는 ‘퍼널(깔때기)’ 관점을 따라갑니다. 거의 접하지 않은 사람부터 일상 사용자, 전문 사용자, 내부 시스템에 접근하는 사람까지, 각 집단이 바라보는 AI의 모습을 정리합니다. 카파시가 제시하는 설명은 맡기는 문제의 크기와 기간, 분야별로 고르지 않은 능력, 그리고 시스템 접근권입니다. 에이전트의 작업 속도와 인간의 검토 사이에 생기는 간극도 함께 다룹니다.…
평범한 사업가
AI 에이전트, 자동화, 바이브코딩을 실전 비즈니스에 적용하는 방법을 다룹니다. 평범한 사업가는 Claude Code, Codex, n8n, AI 에이전트, 하네스 엔지니어링, AI 생산성 도구를 실제 업무와 수익화에 연결하는 채널입니다. 주요 콘텐츠…
3.5×Score at discovery
5.3KViews
1.5KMedian · 10 videos
Outlier score
This score was measured on Thu, 29 Oct 2026 02:00:02 GMT. Current view counts may differ.
5.3K views ÷ a 1.5K baseline = 3.5×. Compared with 10 earlier videos from the same channel, matching the format recorded at scoring time. Older-upload baseline: reference videos had at least as long to gain views. This comparison is not age-matched.
YouTube snapshot: Thu, 29 Oct 2026 04:25:56 GMT. Counters may have changed.
Read the methodologyGenerative AI & Agents
Channel-balanced percentile: 31
Comparison details
31 videos from 19 other channels, with each channel weighted equally. Same format and language, with 10,000–99,999 subscribers. Observed at 403 hours after publication, within ±48 hours.
This describes the collected sample, not all of YouTube. Updated Thu, 29 Oct 2026 04:43:23 GMT.
Niches & tags
Transcripts and detailed analytics are available for recent outlier Shorts up to three minutes. Research tools
Breakouts from other channels
33.6×
Score at discovery · 2026-10-26
Percentile 100 · Generative AI & AgentsAI 에이전트, 어렵게 생각했는데 직접 만들어보니
생존AI31.6K
8.4×
Score at discovery · 2026-10-26
Percentile 100 · Generative AI & Agents오늘, 파워포인트·엑셀·포토샵가 전부 죽었습니다
스마트대디_SmartDaddy97.1K
15.3×
Score at discovery · 2026-10-27
Percentile 100 · Generative AI & Agents한 번 배우면 인생이 편해지는 제미나이 핵심 기능 11개 꿀팁 (+프롬프트 가이드 무료 제공)
조팀장의 AI 공략집87.6K